Engineering Insights

Deep dives into software architecture, cloud infrastructure, and scalable system design.

· 7 min read · · Featured ·

A linter for judgment calls: keeping a codebase clean with a decision model

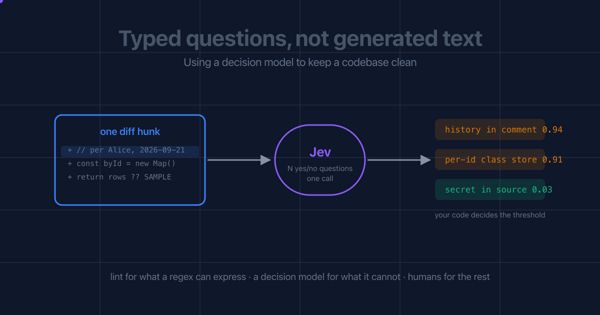
Most of what makes a codebase rot is not hard to describe. A comment that records who asked for a change instead of why the code is that way. Sample data that leaks into a production screen. A test that passes because it skipped. A "temporary" per-record override that quietly becomes a second source of truth. Every team can write these rules down. The problem is that most of them cannot be expressed as a regex, so they live in a wiki, get enforced by whoever happens to be reviewing, and drift.

Jev, TypeSafe's "System One" model, turns out to be a good fit for exactly this gap. It does not generate text. You hand it a small piece of state and a set of typed yes/no questions, and it returns a calibrated probability for each. That shape is what a linter for judgment calls needs.
A linter for judgment calls: keeping a codebase clean with a decision model
· 5 min read · · Featured ·

AI Governance in Two Sentences

I use coding agents every day. Having an agent write a fix and run the tests is useful. Having it run a shell with access to credentials is also a security decision, whether I’m thinking about it at the time or not.

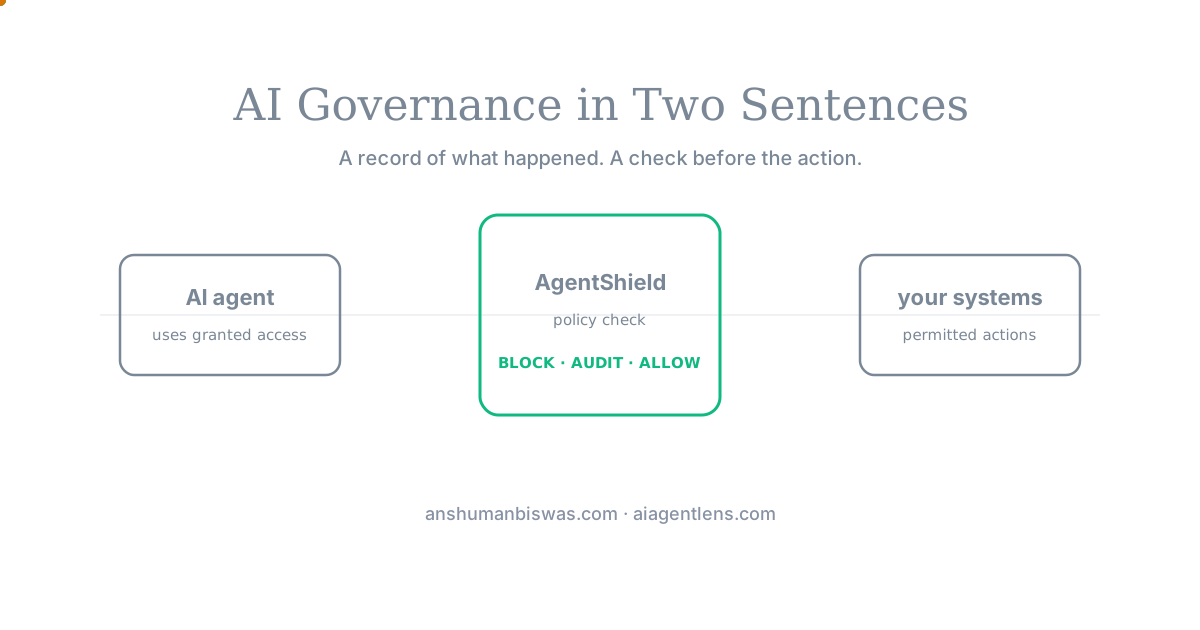
When people ask me what AI governance means for a team using these tools, I start with two responsibilities:

You can explain what your agents did. You can stop actions they should not take.

There is more to governance than that, but those two sentences give us something concrete to examine.

AI Governance in Two Sentences
· 10 min read · ·

The Verdict Is the Easy Part

Two days ago we put a paste box on the open internet. Type a shell command, hit Evaluate, get a verdict — BLOCK, AUDIT, or ALLOW. Same on a second tab for MCP tool calls: tool name, JSON-style args, evaluate, verdict.

The Verdict Is the Easy Part